What Is HBM? High Bandwidth Memory for AI GPUs
HBM is high-bandwidth memory — tall stacks of DRAM beside an AI GPU. How it works, how generations differ, and where money sticks when it binds.

HBM is high-bandwidth memory — tall stacks of DRAM placed beside an AI GPU so data can move fast enough to keep the chip busy.
The money link: who gets paid when AI GPUs need matched memory, where allocation and qualification bind, and how to tell a loud price ask from bits that leave the fab. Mechanism — not a scorecard of names.
EXPLAINEDLast reviewed: 03 Oct 2026Next review: after next SK hynix / Samsung / Micron HBM earnings or 2027 HBM contract print
In short: HBM sits next to the compute die inside one package. Regular server DRAM sits farther away on the board. When HBM is scarce, finished accelerators wait, packaging slots slip, and hyperscaler or neocloud fleets grow more slowly. Cash sticks at the memory makers and the attach step until qualified stacks ship — a price ask is not the same as bits that leave the fab.
Education only. Not investment advice. Do your own research.
What is HBM?
Bandwidth is how much data can move each second. HBM is DRAM built as tall stacks of dies linked by vertical connections, then placed directly beside the GPU inside an advanced package. That short path is why modern AI accelerators are designed around it. See the semiconductors stack for how this memory gate sits next to packaging and foundry.
For how HBM compares with the GDDR7 graphics memory on a board, see HBM vs GDDR7.
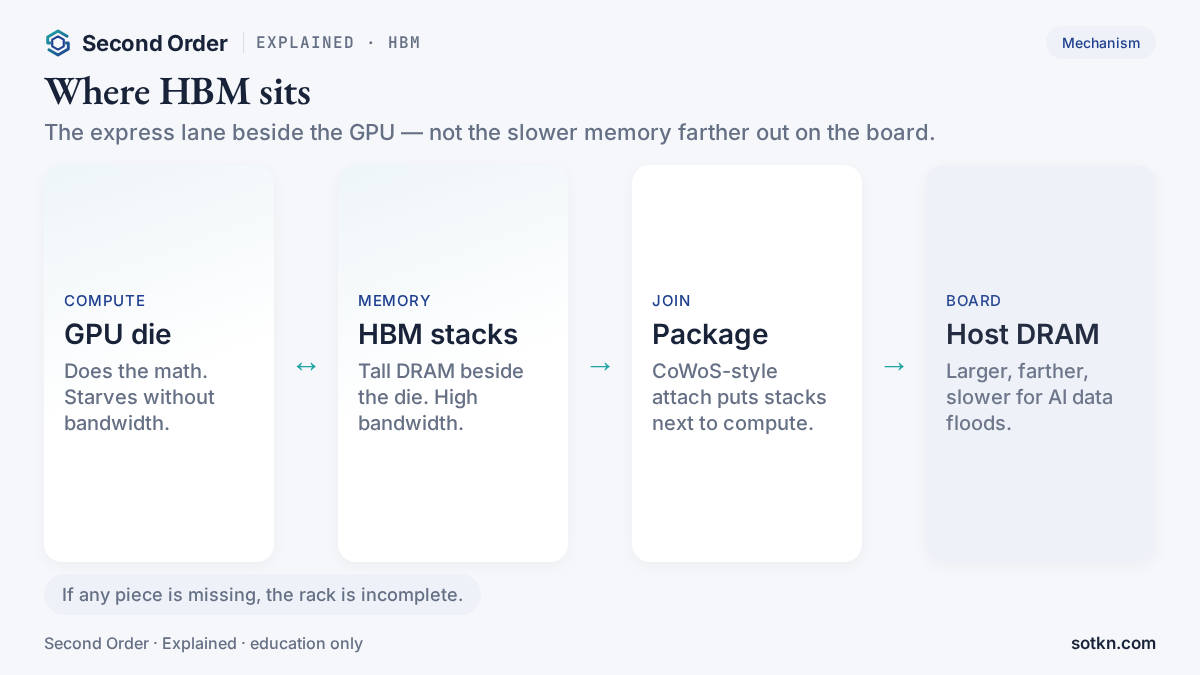
| Layer | Role | Speed read |
|---|---|---|
| GPU die | Does the math | Starves without nearby bandwidth |
| HBM stacks | Tall DRAM beside the die | Express lane for AI data floods |
| Package | CoWoS-class attach | Puts stacks next to compute |
| Host DRAM | Board memory | Larger, farther, slower |
HBM vs DDR: what is the difference?
Both are DRAM. The difference is where they sit and how wide the pipe is. HBM is the nearby express lane inside the package. DDR-class host memory is the larger warehouse on the board. AI training and inference need both — but the GPU waits first when the nearby lane is short. For a dedicated versus page see HBM vs DDR5.
| HBM | DDR / host DRAM | |
|---|---|---|
| Location | Beside the GPU inside the package | On the server board, farther away |
| Job | Feed the accelerator at high bandwidth | Hold large working sets and system data |
| Build | Tall stacks, vertical links, tight attach | Modules and sockets; simpler to expand |
| When scarce | Finished GPUs under-ship | Servers still build; AI pods stay thin |
| Who invoices first | Memory makers with qualified stacks | Broader DRAM suppliers |
Why do AI GPUs need HBM?
Modern models move enormous amounts of data while they train and while they answer queries. The GPU computes very fast. If memory cannot keep up, the GPU waits — and waiting wastes the most expensive component in the building.
HBM helps in three ways: speed (high bandwidth between memory and compute), closeness (short distance inside the package), and density (stacking upward to fit more bits beside the chip). Each accelerator generation tends to attach more HBM, or faster HBM. Memory bits per GPU can rise even when unit shipments are flat. That is why rising AI CapEx at hyperscalers and neoclouds shows up as HBM demand with lag.
HBM3E vs HBM4: what changes?
You will see labels like HBM3E and HBM4. A generation step is a product change along stack height, interface speed, and capacity per stack — not a marketing rename.
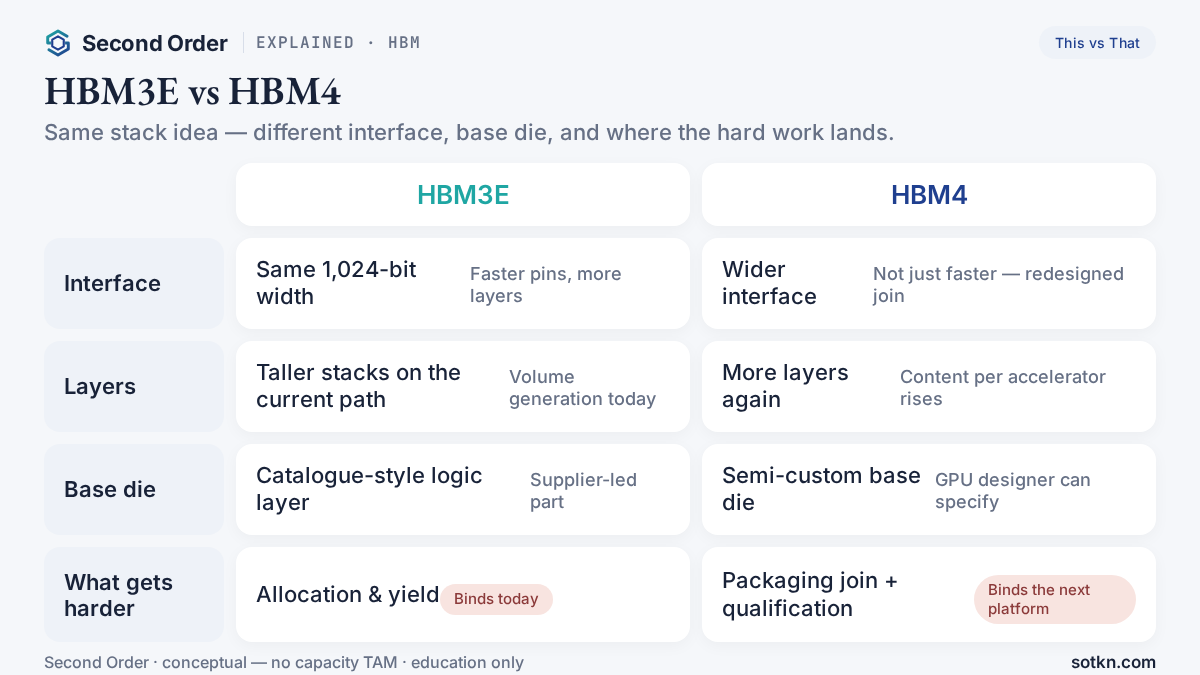
| Axis | HBM3E | HBM4 (JESD270-4) |
|---|---|---|
| Interface | Same 1,024-bit-class path; faster pins | Wider path — JEDEC cites up to 8 Gb/s across a 2048-bit interface, up to 2 TB/s per stack (Apr 2025) |
| Channels | HBM3-class channel count | 32 independent channels (vs 16 in HBM3), per JEDEC |
| Layers / capacity | Taller stacks on the current path | 4- to 16-high; up to 64 GB per cube on 32 Gb 16-High (spec) |
| What binds today | Allocation and yield on volume platforms | Qualification, packaging join, and ramp timing |
JEDEC published the HBM4 standard (JESD270-4) on 16 April 2025 — a generation definition, not a ship calendar. Company IR as of mid-2026: SK hynix said HBM4 mass shipments began in Q2 2026 with a second-half ramp (29 Jul 2026); Micron said volume shipment of HBM4 36GB 12H began in calendar Q1 2026 for NVIDIA Vera Rubin platforms (16 Mar 2026); Samsung reported HBM4 scale-up with Q2 2026 Device Solutions results (30 Jul 2026). Dated company statements only.
HBM3E is still where most near-term AI GPU volume binds. HBM4 is where qualification and packaging risk sit for the next platform wave. A supplier can be sold out on one generation and still be racing on the next — those are different clocks.
Who gets paid when HBM is scarce?
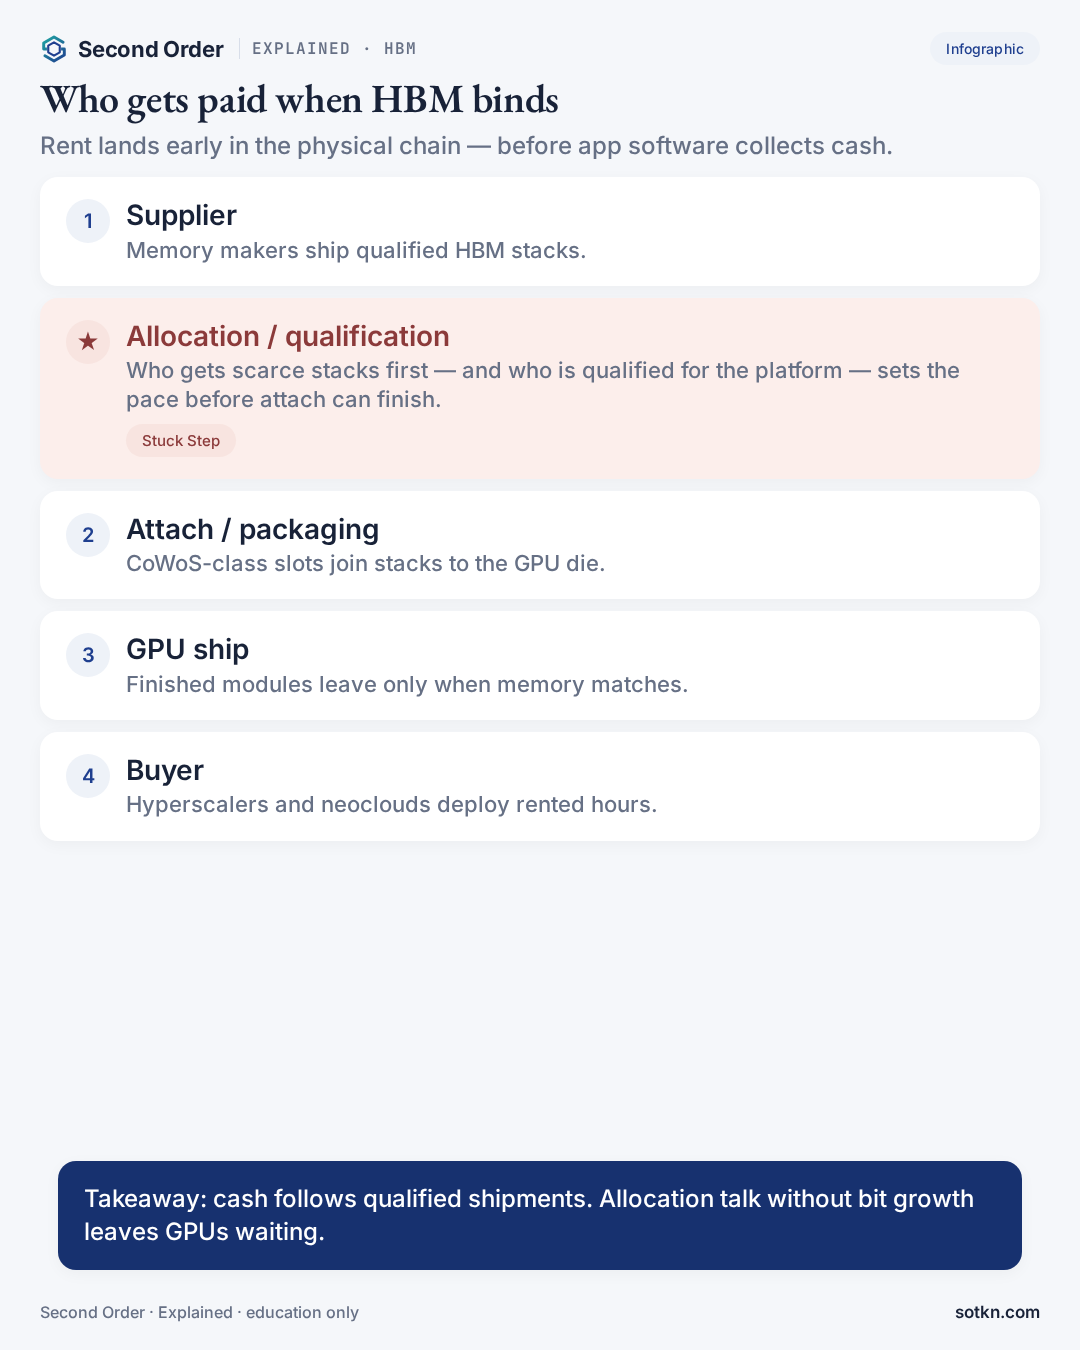
| Step | Who | Why it matters |
|---|---|---|
| Supplier | Memory makers (SK hynix, Samsung, Micron) | Ship qualified stacks |
| Stuck step | Allocation / qualification | Who gets scarce stacks first sets the pace |
| Attach | CoWoS-class packaging | Join stacks to the GPU die |
| GPU ship | Accelerator builders | Modules leave only when memory matches |
| Buyer | Hyperscalers / neoclouds | Deploy capacity after hardware arrives |
Memory makers sit early. Cash ties to bits shipped, advanced-stack mix, and pricing when allocation is tight. Counterpoint’s Q2 2026 HBM revenue-share table put SK hynix / Samsung / Micron at roughly 50% / 33% / 18% — a dated research estimate. SK hynix’s Q2 2026 print: KRW 79.3tn revenue, 76% operating margin on a high-value mix including HBM, ~10 long-term customers (29 Jul 2026). Markets: SK hynix HBM allocation and the Korea market hub.
Price talk is not shipped bits. Maeil Business (2 Oct 2026) reported Samsung offered mid-to-high ~US$4/Gb for 2027 HBM4 contracts — more than triple a ~US$1.50/Gb HBM3E reference in the same piece. That is a reported opening ask, not a settled ASP. Wire: Samsung mid-$4/Gb HBM4 ask. Cash waits on qualification, yield, and contracted stacks.
Wafer share is the quieter clock. Our Analysis If HBM Takes ~30% of DRAM Wafers, Where Does Cash Stick? cites research tracking HBM toward ~30% of top-three DRAM wafer input by late 2027 (bits share much smaller). Treat those percentages as reported estimates — they explain why commodity DRAM feels the squeeze when HBM wins the wafer pool.
When allocation is tight: late HBM slips packaging slots; late packaging leaves HBM inventory sitting. Finished modules delay either way. App software earns later, when models are deployed and users pay.
Allocation talk versus bit growth — how do you tell them apart?
Allocation is who gets scarce stacks first. Bit growth is how many bits actually ship. Supplier commentary is usually loud on the first and quiet on the second. Cash follows shipped stacks, not the loudest sentence in a briefing — and not the first reported contract ask.
| Signal | Tight read | Loose read |
|---|---|---|
| Allocation language | Buyers scramble; premiums hold | Mid-tier access improves |
| Bit-growth disclosure | Flat near-term bits | Rising qualified shipments |
| Price asks | Opening offers high; still negotiating | Settled ASP prints with volumes |
| Attach and packaging | Packages wait on stacks | Stacks and slots move together |
Three combinations: allocation without bit growth delays attach; bit growth without packaging leaves stacks waiting; both easing lets full-spec systems ramp. “Sold out” on one HBM generation is not “all DRAM sold out”.
How do you read an HBM capacity announcement?
Four questions separate a plan from supply: generation (which HBM step?), timing (when does meaningful output arrive?), units (wafers, stacks, or revenue aspiration?), and commitment (are customers already contracted?). Without those four, “more HBM” is a slogan. A mid-$4/Gb ask fails the same test until volumes and qualification land.
How does this differ from the packaging gate?
Advanced packaging is the neighbouring gate. A packaging queue without HBM bits leaves racks under-fed; a memory surge without packaging leaves stacks in crates. Read both clocks — see CoWoS explained. HBM4’s wider interface pushes more risk into attach. On 28 Sep 2026 SK hynix said it won TSMC Partner of the Year for validating HBM5 on CoWoS from early design (newsroom) — validation colour, not volume. Wire: SK hynix HBM5–CoWoS validation.
Legal overhang can colour the door without changing the fab clock. Netlist’s ITC cases on Samsung HBM are import-risk stories — separate from bit-growth prints. See Netlist HBM ITC Wire. Accelerator players: who makes AI chips.
Common misconceptions
- People assume HBM is just faster DDR. Actually it is a different placement and build — tall stacks beside the GPU inside one package, not modules on the board.
- People assume a capacity slide or a mid-$4 ask means open, priced supply this quarter. Actually check generation, timing, units, contracts, and ask vs settled ASP.
- People assume HBM and CoWoS are the same bottleneck. Actually they are neighbours. Either one can bind, often on different clocks — and HBM5–CoWoS validation is not volume.
- People assume sold-out HBM means all memory is scarce. Actually older PC or phone DRAM can look freer while premium HBM stays allocated — and HBM’s wafer share can still squeeze the commodity pool.
Not investment advice. Do your own research.
FAQ
What is HBM?
HBM is high-bandwidth memory — DRAM built in tall stacks and placed beside the GPU inside one package so data can move fast enough to keep the chip busy.
What does HBM stand for?
High-bandwidth memory (sometimes written high bandwidth memory).
Why do AI GPUs need HBM?
Because the GPU can compute faster than ordinary board memory can feed it. Without enough nearby bandwidth, the accelerator waits and finished systems under-ship.
What is the difference between HBM and DDR?
HBM sits beside the GPU inside the package as a high-bandwidth lane. DDR-class host DRAM sits on the board as larger, farther memory. AI systems usually need both.
Who makes HBM?
SK hynix, Samsung, and Micron are the three major suppliers tracked in public share tables. Counterpoint put them at roughly 50% / 33% / 18% of HBM revenue in Q2 2026.
What is the difference between HBM3E and HBM4?
HBM3E extends HBM3 on the current interface path with more layers and speed. HBM4 (JEDEC JESD270-4, Apr 2025) widens the interface and raises channel count and stack options — which moves more difficulty into packaging and qualification.
Is HBM the same as the packaging bottleneck?
No. Packaging joins the stack to the compute die. Either gate can bind, often at different times. SK hynix’s Sep 2026 HBM5–CoWoS validation with TSMC is early attach work — not volume shipment.
Does a mid-$4/Gb HBM4 ask mean supply is priced?
Not yet. A reported opening ask (Samsung / Maeil Business, 2 Oct 2026) is negotiation colour. Cash follows qualified stacks under contract.
Related terms
- CoWoS — packaging twin that joins stacks to the GPU.
- EUV lithography — patterning step upstream of advanced memory and logic.
- HBM vs DDR5 — versus page for the nearby lane vs board memory.
- Hyperscaler — CapEx dial that sets AI memory demand with lag.
- Neocloud — specialist GPU cloud that feels HBM scarcity as delayed hours.
- Who makes AI chips — players along the accelerator bill of materials.
- Neoclouds stack — specialist GPU capacity layer above scarcity.
How we check this
Figures come from company filings and government releases, each dated in the list below. Capacity and timing from press reports are labelled as reported, not guided. Where we work something out ourselves, the arithmetic is shown in full.
Last reviewed: 03 Oct 2026 · Next review: after next SK hynix / Samsung / Micron HBM earnings or 2027 HBM contract print
Spot an error? Tell us and we will correct it and note the change here.
Sources
- JEDEC — JESD270-4 HBM4 standard press release (16 Apr 2025)
- SK hynix — Q2 2026 business results (29 Jul 2026)
- Micron — HBM4 high-volume production PR (16 Mar 2026)
- Samsung Electronics — Q2 2026 results (30 Jul 2026)
- SK hynix — TSMC OIP Conference; HBM5–CoWoS Partner of the Year (28 Sep 2026)
- Maeil Business — Samsung mid-to-high ~US$4/Gb HBM4 ask for 2027 (2 Oct 2026; reported)
- Counterpoint Research — Global DRAM and HBM market share (Q2 2026 table)