HBM vs GDDR
HBM stacks beside the GPU on advanced packaging; GDDR sits as discrete chips on the board. Same memory family tree — different stuck step and who gets paid.
EXPLAINEDLast reviewed: 22 September 2026Next review: after next JEDEC HBM/GDDR update or NVIDIA memory-roadmap note
HBM vs GDDR is the contrast between high-bandwidth memory stacked beside an AI accelerator on advanced packaging and graphics DRAM soldered as discrete chips on the board.
In short: HBM is stacked beside the GPU on advanced packaging. GDDR is planar graphics DRAM on the board. AI training and flagship inference pay the HBM + packaging path; gaming and cost-efficient inference often stay on GDDR. Who gets paid and which step sticks are different.
For investors watching the Semiconductors layer, the money link is simple: who gets paid when AI CapEx binds scarce HBM stacks and packaging, versus who gets paid when board-level GDDR ships without that gate.
What is the difference between HBM and GDDR?
HBM (high bandwidth memory) stacks DRAM dies vertically with through-silicon vias and sits beside the GPU on an interposer or advanced package. GDDR (graphics double data rate) is planar graphics DRAM soldered as discrete chips on the PCB. That attach difference drives bandwidth density, packaging cost, power per bit, and which suppliers clear first when AI orders hit.
| Axis | HBM | GDDR |
|---|---|---|
| Physical attach | Stacked DRAM on interposer / advanced package | Discrete BGA chips on the PCB |
| Bus style | Very wide, slower per pin (package-level) | Narrower, very fast per pin (board-level) |
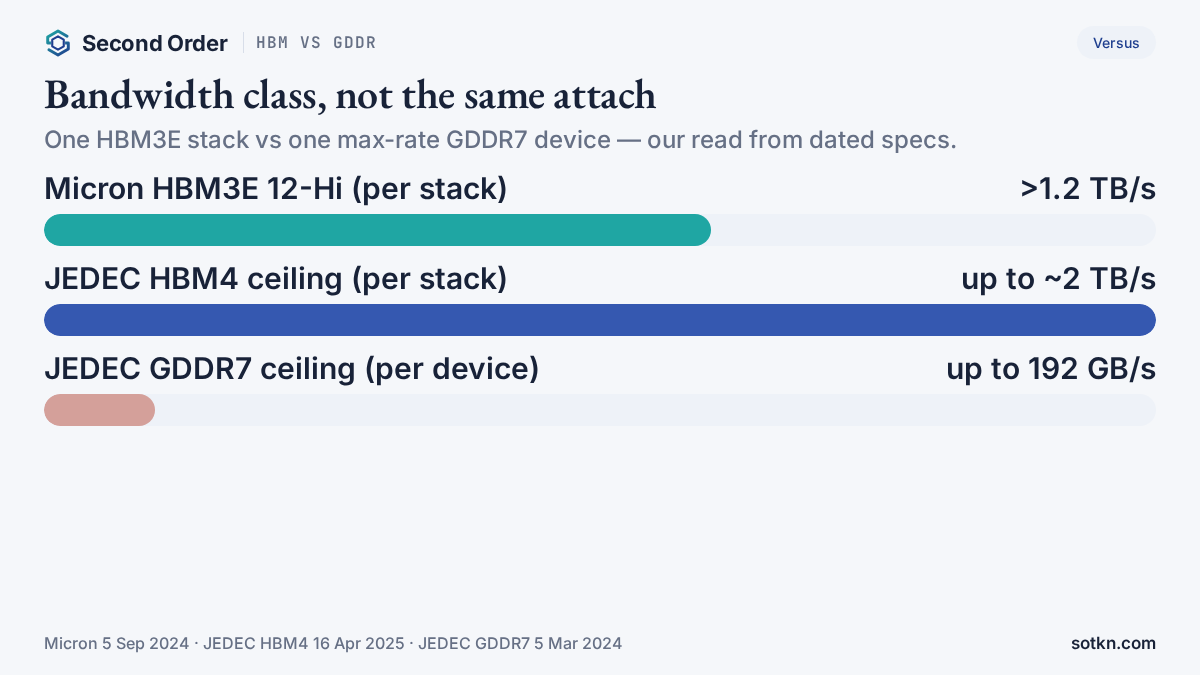
| Bandwidth class | ~1.2 TB/s/stack HBM3E (Micron 5 Sep 2024); HBM4 up to ~2 TB/s (JEDEC 16 Apr 2025) | JEDEC GDDR7 up to 192 GB/s/device (5 Mar 2024); scales with bus × chips |
| Typical AI use | Training / flagship inference (e.g. H200 141 GB @ 4.8 TB/s) | Graphics / cost-efficient inference (e.g. Rubin CPX 128 GB GDDR7) |
| Packaging tax | CoWoS / interposer / hybrid-bond economics | Standard SMT / board routing |
| Who gets paid | HBM + packaging when CapEx binds stacks | GDDR suppliers when board-level GPUs ship |
| Stuck step | Stack supply + packaging slots | Pin-speed / board design — not CoWoS |
See the semiconductors stack for how memory sits next to packaging and accelerators, and what CoWoS packaging is for the HBM attach gate.
When does each win?
HBM wins when the workload saturates multi-TB/s on package — training and flagship inference. NVIDIA’s H200 lists 141 GB HBM3e at 4.8 TB/s (product page). Blackwell Ultra reaches 288 GB HBM3E at 8 TB/s (NVIDIA Technical Blog).
GDDR wins when the design needs board-level bandwidth without the interposer and CoWoS-class packaging tax. JEDEC published GDDR7 on 5 March 2024 at up to 192 GB/s per device. NVIDIA’s Rubin CPX (9 Sep 2025) pairs 128 GB of cost-efficient GDDR7 with a context-phase GPU — availability expected end-2026 (forward-looking).
Fleets often use both tiers: training still pulls HBM; long-context or cost-sensitive inference can sit on GDDR when the roadmap says so.
Who gets paid — and where money sticks?
On the HBM path, cash sticks when AI CapEx binds memory suppliers and advanced packaging. SK hynix began mass production of 12-layer HBM3E at 36 GB and 9.6 Gbps on 26 September 2024 (company-reported). Micron’s HBM3E 12-high claims more than 1.2 TB/s at pin speeds above 9.2 Gb/s (5 Sep 2024).
Our arithmetic from those dated ceilings: one Micron HBM3E stack at >1.2 TB/s versus one JEDEC-max GDDR7 device at 0.192 TB/s is about 6× (1.2 ÷ 0.192 ≈ 6.25). JEDEC HBM4’s ~2 TB/s stack ceiling is about 10× one max-rate GDDR7 device. That is stack-versus-device math — system bandwidth still depends on stack or chip count.
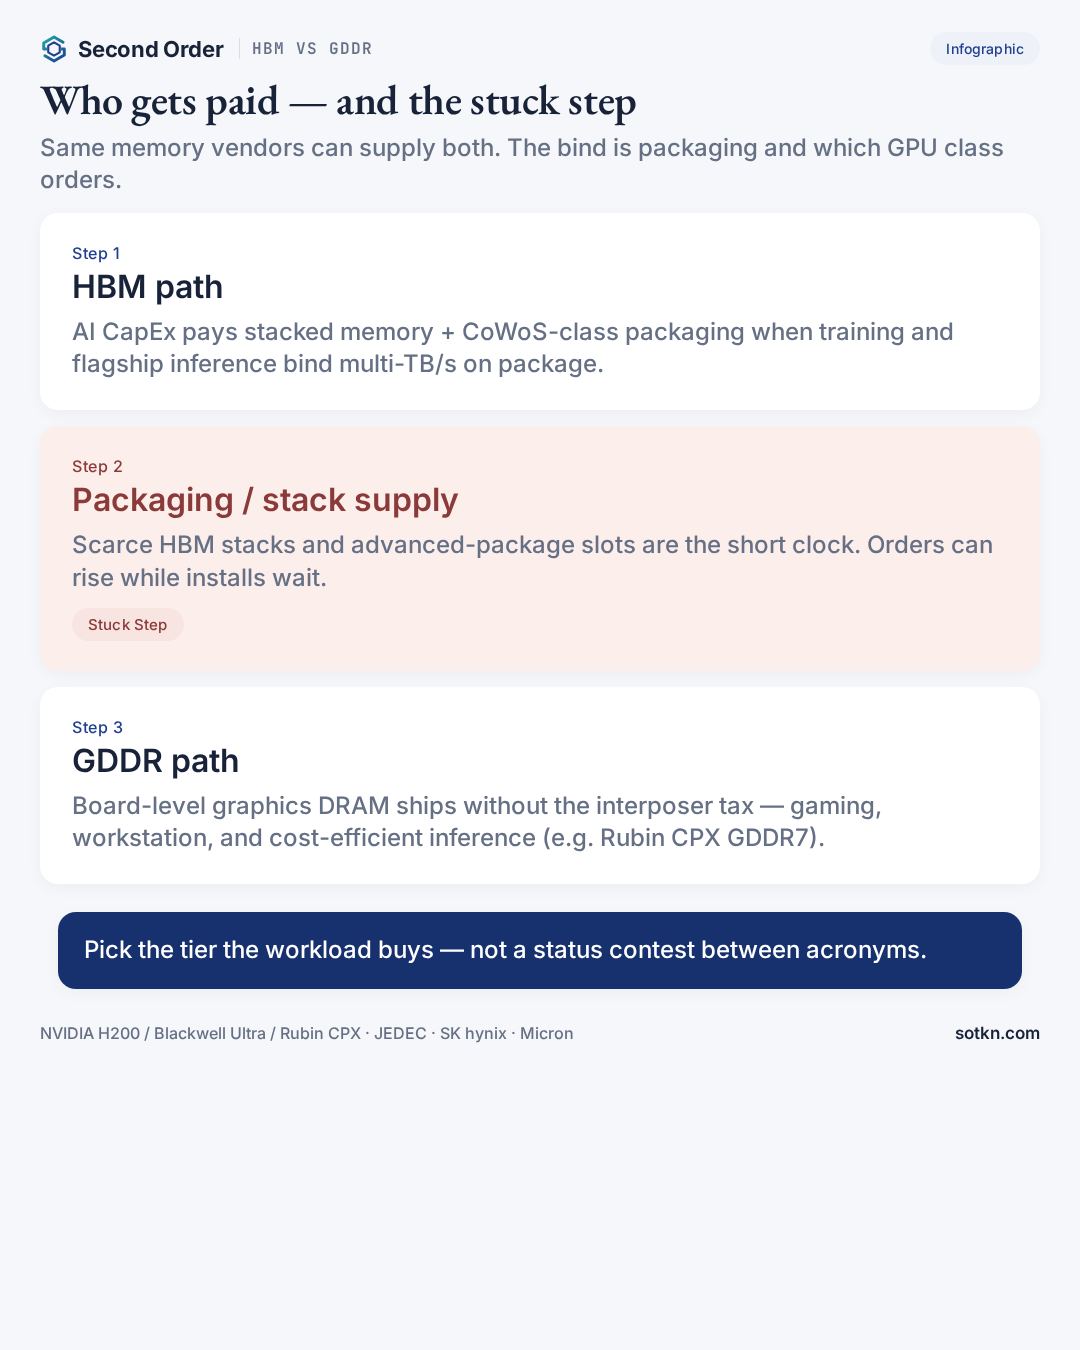
| Step | HBM path | GDDR path |
|---|---|---|
| Who gets paid first | Memory makers and packaging lines when AI accelerator BOM orders bind | GDDR makers when graphics and cost-efficient accelerator boards ship |
| Where money sticks | Scarce HBM stacks and CoWoS-class finish lines with lag | Board-level DRAM volume without the interposer tax |
| Stuck step | Orders vs installs — CapEx can rise while stacks and package slots wait | Rarely the same packaging bind; elastic when pin-speed and wafers clear |
Markets door for Korea memory allocation: Korea HBM — who gets paid when AI memory stays scarce.
How does power and packaging compare?
HBM’s edge is bandwidth density at the package when workloads saturate multi-TB/s. GDDR7’s edge is board-level bandwidth with PAM3 and standard SMT economics (JEDEC, 5 Mar 2024). The second-order clock: HBM demand hits CoWoS-class slots; GDDR demand mostly does not.
Common misconceptions
- People assume the same “graphics memory” label means the same business. Actually HBM and GDDR share a DRAM family tree but diverge on attach, packaging tax, and which CapEx line clears first.
- People assume GDDR7 replaces HBM on training BOMs. Actually NVIDIA’s Rubin CPX language treats GDDR7 as cost-efficient memory for a context-phase GPU while flagship parts stay on HBM (9 Sep 2025).
- People assume one big bandwidth number settles the debate. Actually compare stack versus device carefully. System bandwidth is stacks × rate or bus width × pin speed × chip count.
- People assume JEDEC ceilings equal shipping SKUs. Actually standards set envelopes. Vendor bins and GPU product pages are the shipping claims — labelled as company-reported.
FAQ
What is the difference between HBM and GDDR?
HBM is stacked DRAM on a silicon interposer or advanced package beside the GPU. GDDR is planar graphics DRAM soldered to the board. Bandwidth class, packaging cost, and who gets paid diverge from that attach.
Is HBM faster than GDDR?
Per stack, yes in the AI class: Micron’s HBM3E 12-high claims >1.2 TB/s (5 Sep 2024); JEDEC GDDR7 tops out at 192 GB/s per device (5 Mar 2024). System bandwidth still depends on stack or device count.
When does GDDR win versus HBM?
GDDR wins when the design needs board-level bandwidth without the interposer tax — gaming, workstations, and cost-efficient inference such as NVIDIA’s announced Rubin CPX with 128 GB GDDR7 (9 Sep 2025).
Why do AI training GPUs use HBM?
Training and flagship inference need multi-TB/s on package. NVIDIA’s H200 lists 141 GB HBM3e at 4.8 TB/s; Blackwell Ultra reaches 288 GB HBM3E at 8 TB/s.
Who gets paid in the HBM path versus the GDDR path?
HBM path: memory suppliers and advanced packaging when CapEx binds stacks and CoWoS slots. GDDR path: graphics-DRAM suppliers when board-level accelerators ship without that gate.
Does GDDR replace HBM for AI?
No. NVIDIA’s Rubin CPX language calls GDDR7 cost-efficient for a context-phase GPU (9 Sep 2025) while flagship Rubin stays on HBM. Buy the tier the workload needs.
Related terms
- HBM — high bandwidth memory stacked beside AI GPUs.
- CoWoS — the packaging gate that often sits next to HBM.
- Memory process tools — equipment that gates how fast HBM capacity can rise.
Markets and stack doors
Layer: semiconductors. Markets: Korea HBM memory.
Further reading
Get the Wire — short notes when memory or packaging clocks move.
How we check this
Figures come from company filings and government releases, each dated in the list below. Capacity and timing from press reports are labelled as reported, not guided. Where we work something out ourselves, the arithmetic is shown in full.
Last reviewed: 22 Sep 2026 · Next review: after next JEDEC HBM/GDDR update or NVIDIA memory-roadmap note
Spot an error? Tell us and we will correct it and note the change here.
Sources
- JEDEC — publishes GDDR7 (JESD239); up to 192 GB/s per device (5 Mar 2024)
- BusinessWire / JEDEC — HBM4 (JESD270-4); up to ~2 TB/s on 2048-bit, up to 64 GB/stack (16 Apr 2025)
- NVIDIA H200 — 141 GB HBM3e at 4.8 TB/s (product page, accessed 22 Sep 2026)
- NVIDIA Technical Blog — Blackwell Ultra: 288 GB HBM3E, 8 TB/s
- NVIDIA Newsroom — Rubin CPX: 128 GB cost-efficient GDDR7; expected end-2026 (9 Sep 2025)
- SK hynix — mass production of 12-layer HBM3E 36 GB at 9.6 Gbps (26 Sep 2024)
- Micron — HBM3E 12-high 36 GB; >1.2 TB/s at >9.2 Gb/s (5 Sep 2024)